# For each task/tool, I include a number of prompts I imagine a user might use to implore the AI to perform
# that task.  When I build the actually examples, I randomly grab a single item for each task that should
# be called to build the final user prompt
example_translation_asks = [
    "If the text below is not in English, translate it into English; otherwise, return the text as is",
    "Translate the text below into English if it is not already in English; if it is, return it unchanged",
    "If the provided text is in a language other than English, translate it to English; if it's already in English, return it without changes",  # noqa: E501
    "Translate the following text to English if it is not written in English; otherwise, leave it unaltered",
    "If the text below is not in English, convert it to English; if it is in English, return it without modification",
]

example_summarization_asks = [
    "Provide a short summary of the text below and identify any overarching themes",
    "Summarize the document below and highlight any broad themes present",
    "Create a concise summary of the following document and identify any general themes",
    "Extract a brief 1-2 sentence summary from the text below and determine any broad themes",
    "Summarize the text below in 1-2 sentences and identify any major themes within it",
]
example_ner_asks = [
    "Extract the named entities from the author's statement below",
    "Determine the named entities in the document below",
    "Identify the specific named entities in the statement below",
    "Perform NER on the text below",
    "Do NER on the document below",
]
example_sentiment_asks = [
    "Determine the sentiment expressed in the document below",
    "Do sentiment analysis on the text below",
    "Identify and classify the sentiments expressed in the following document",
    "Perform sentiment analysis on the document below",
    "Extract the sentiment from the document below",
]
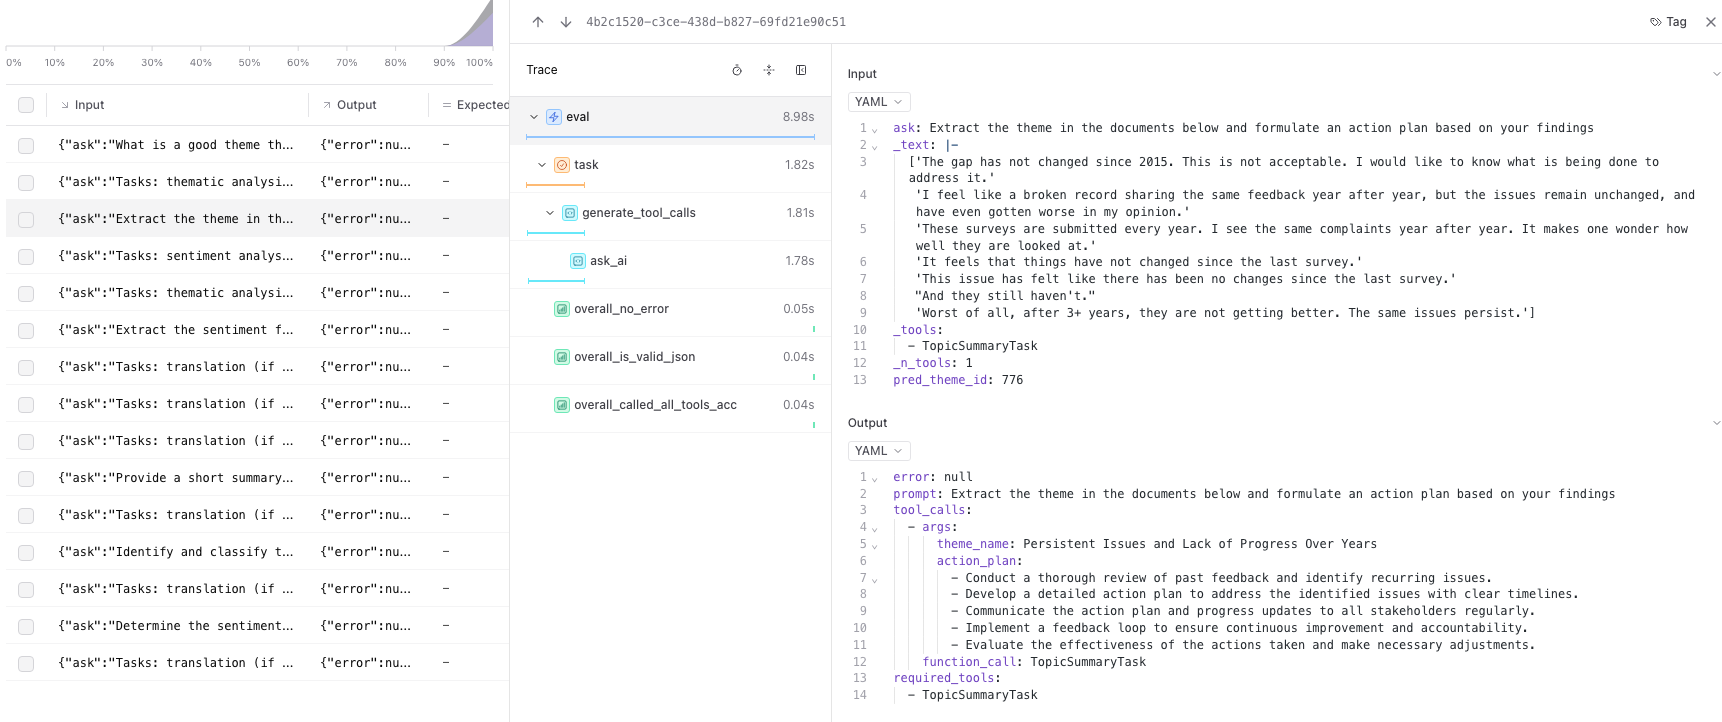
example_theme_asks = [
    "Identify the theme in the documents below and create an action plan based on them",
    "Determine the theme in the provided documents and develop an action plan accordingly",
    "Extract the theme in the documents below and formulate an action plan based on your findings",
    "Based on the documents provided, extract their theme and an action plan based on them",
    "What is a good theme that describes the text below? Also include an action plan based on the provided documents",
]


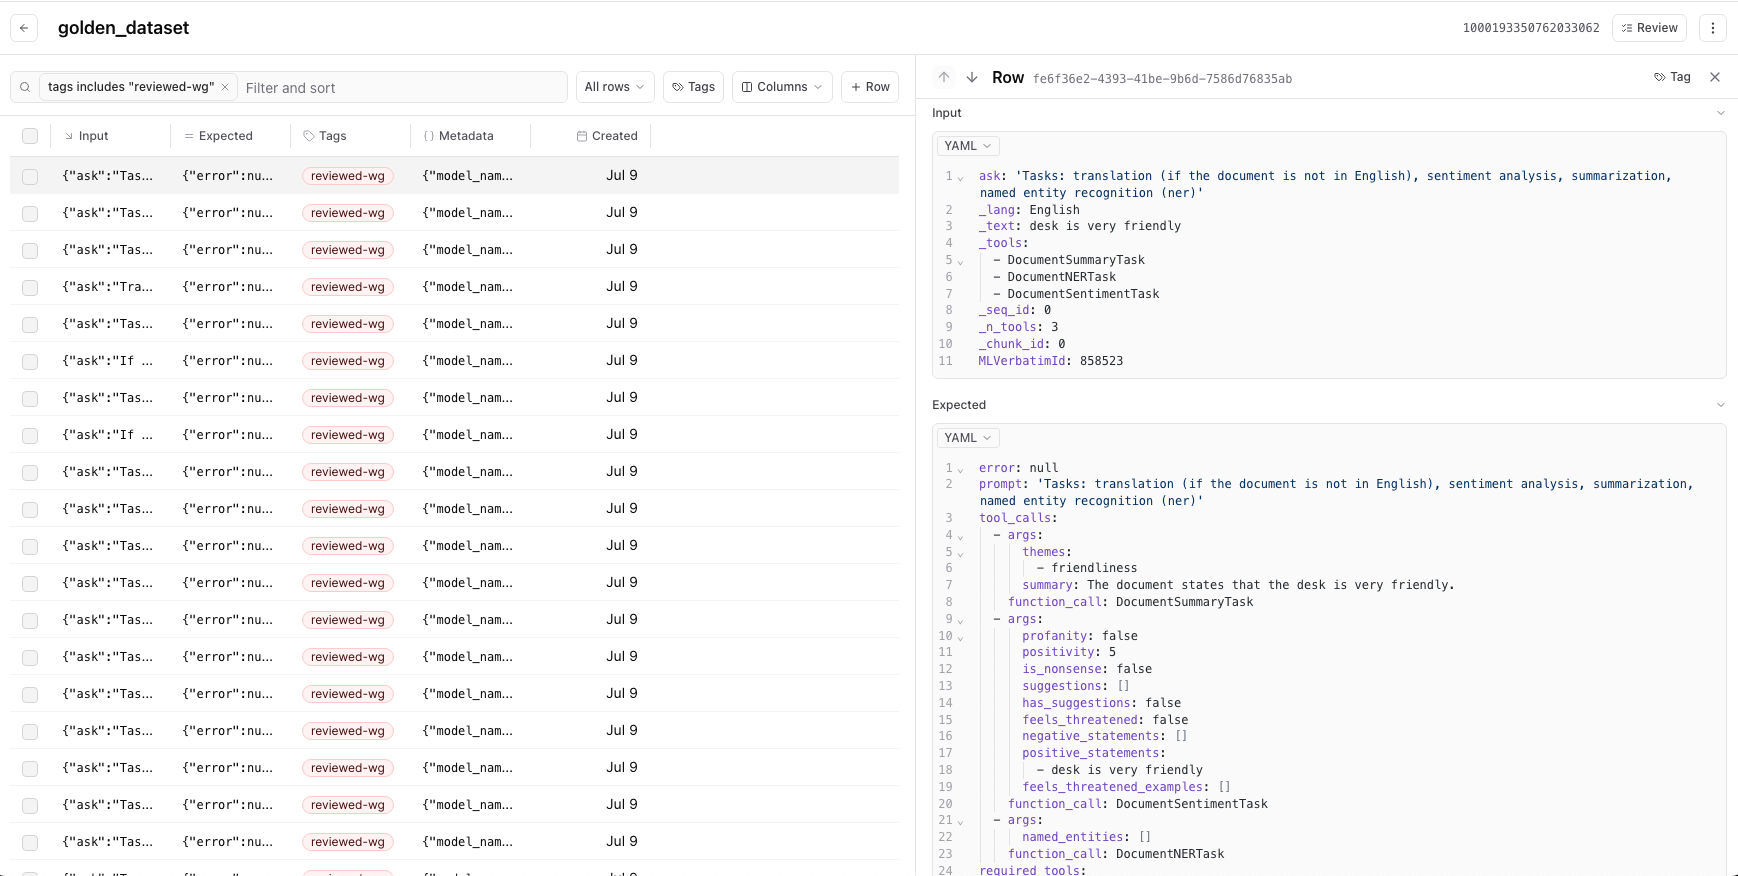
# Given a list of tools to call and whether our context is a single document or a colleciton of documents,
# this utility function does the work of coallesicing all the asks into a single human prompt.  Note how
# for "translation" tasks we sometimes ask for translation specifically and at other times we don't because
# I hope that ultimately, the model can just see the text is not in English and do the translation task
# without being specifically asked too.
def build_hypothetical_prompt(tool_names, is_doc: bool = False):
    # Vary the overall format of the prompt for different styles by which a user may ask for
    # different tasks
    if random.choice([True, False]):
        queries = []
        for tool_name in tool_names:
            if tool_name == "TranslationTask":
                # Vary this being asked explicity so model can learn to call this tool whenver
                # it detects a non-English document
                if random.choice([True, False]):
                    queries.append(random.choice(example_translation_asks))
            elif tool_name == "DocumentSummaryTask":
                queries.append(random.choice(example_summarization_asks))
            elif tool_name == "DocumentNERTask":
                queries.append(random.choice(example_ner_asks))
            elif tool_name == "DocumentSentimentTask":
                queries.append(random.choice(example_sentiment_asks))
            elif tool_name == "TopicSummaryTask":
                queries.append(random.choice(example_theme_asks))

        prompt = queries[0]
        for q in queries[1:]:
            prompt += f". {q}"
    else:
        tasks = []
        for tool_name in tool_names:
            if tool_name == "DocumentSummaryTask":
                tasks.append("summarization")
            elif tool_name == "DocumentNERTask":
                tasks.append("named entity recognition (ner)")
            elif tool_name == "DocumentSentimentTask":
                tasks.append("sentiment analysis")
            elif tool_name == "TopicSummaryTask":
                tasks.append("thematic analysis/action planning")

        random.shuffle(tasks)

        if is_doc:
            tasks.insert(0, "translation (if the document is not in English)")

        prompt = f"Tasks: {', '.join(tasks)}"

    return prompt.strip()


# When building examples, I use these weights to ensure some tasks are more frequently asked for than
# others. I'm doing this because it's my observation that this is what is more likely to be seen at
# inference time.
def get_tool_option_weights(tool_options: list[str]):
    weights = [
        0.1 if i == 1 else 0.9 / (len(tool_options) - 1)
        for i in range(1, len(tool_options) + 1)
    ]
    return weights


# This is the function that will be called to build a sampled dataset. It's designed to give the
# developer the ability to determine how many, and of what type, of data it should get from the
# document datasets created earlier. It also determines a random number of tools to call and
# includes that information in the dataset to be used for evals (e.g., testing that all expected
# tools were called, etc...)
def get_sample(
    docs_df: pd.DataFrame,
    topics_df: pd.DataFrame,
    n_docs: int = 5,
    n_docs_non_english: int = 2,
    n_chunks: int = 5,
    n_topics: int = 5,
    random_state: int | None = None,
):
    random.seed(random_state)

    # Add in some full and chunked documents for single document analysis
    df = docs_df.copy()
    test_df = df[df["AnswerLang"] == "Spanish"].sample(
        n=n_docs_non_english, random_state=random_state
    )
    test_df["AnswerText"] = test_df["AnswerText_NonEnglish"]
    test_df = pd.concat(
        [
            test_df,
            df[df["AnswerLang"] == "English"].sample(
                n=n_docs, random_state=random_state
            ),
        ]
    )
    test_df["_seq_id"] = -1
    test_df["_chunk_id"] = -1
    test_df = test_df.rename(columns={"AnswerText": "_text", "AnswerLang": "_lang"})
    test_df = test_df[["MLVerbatimId", "_seq_id", "_chunk_id", "_text", "_lang"]]

    chunk_df = df.sample(n=n_chunks, random_state=random_state)
    chunk_df = chunk_df.rename(columns={"_chunk": "_text", "AnswerLang": "_lang"})
    chunk_df["_lang"] = "English"
    chunk_df = chunk_df[["MLVerbatimId", "_seq_id", "_chunk_id", "_text", "_lang"]]

    test_df = pd.concat([test_df, chunk_df])
    test_df = test_df.drop_duplicates(subset=["_text"], keep="first")

    # Get a list as of dicts
    test_data_d = test_df.to_dict(orient="records")

    # Randomize the tools and the number of tools being called for variety
    tool_options = ["DocumentSummaryTask", "DocumentNERTask", "DocumentSentimentTask"]
    tool_option_weights = get_tool_option_weights(tool_options)
    for example in test_data_d:
        tools_to_call = []
        if example["_lang"] != "English":
            tools_to_call.append("TranslationTask")

        n_tools = random.choices(
            range(1, len(tool_options) + 1), weights=tool_option_weights, k=1
        )[0]
        tools_to_call += random.sample(tool_options, n_tools)

        if len(example["_text"]) >= 940:
            # For longer documents, vary the inclusion of 'TopicSummary'
            if random.choice([True, False]):
                tools_to_call.append("TopicSummaryTask")

        example["_n_tools"] = len(tools_to_call)
        example["_tools"] = tools_to_call
        example["ask"] = build_hypothetical_prompt(tools_to_call, is_doc=True)

    # Add in some summaries for related document analsysis
    df = topics_df.copy()
    test_df = df[df["pred_theme_id"] != -1].sample(
        n=n_topics, random_state=random_state
    )
    test_df = test_df.rename(columns={"_chunk": "_text"})
    test_df = test_df[["pred_theme_id", "_text"]]

    test_df = test_df.drop_duplicates(subset=["_text"], keep="first")

    # Get a list as of dicts
    topics_test_data_d = test_df.to_dict(orient="records")

    # Randomize the tools and the number of tools being called for variety
    for example in topics_test_data_d:
        tools_to_call = ["TopicSummaryTask"]
        # Randomly throw in the sentiment task 'DocumentSentimentTask'
        if random.choice([True, False]):
            tools_to_call.append("DocumentSentimentTask")

        example["_n_tools"] = len(tools_to_call)
        example["_tools"] = tools_to_call
        example["ask"] = build_hypothetical_prompt(tools_to_call, is_doc=False)

    return test_data_d + topics_test_data_d